HTML returns but styling stays old
Compare document version, CSS URL and the actual file received. Inspect the relevant cache before repeated purges. Restore a coherent set and check the photographs and scripts used by that version.
In-depth practical guides
Define what must roll back, retain a coherent version and verify recovery: a practical plan for files, data, languages, caches and user journeys.
Updated :
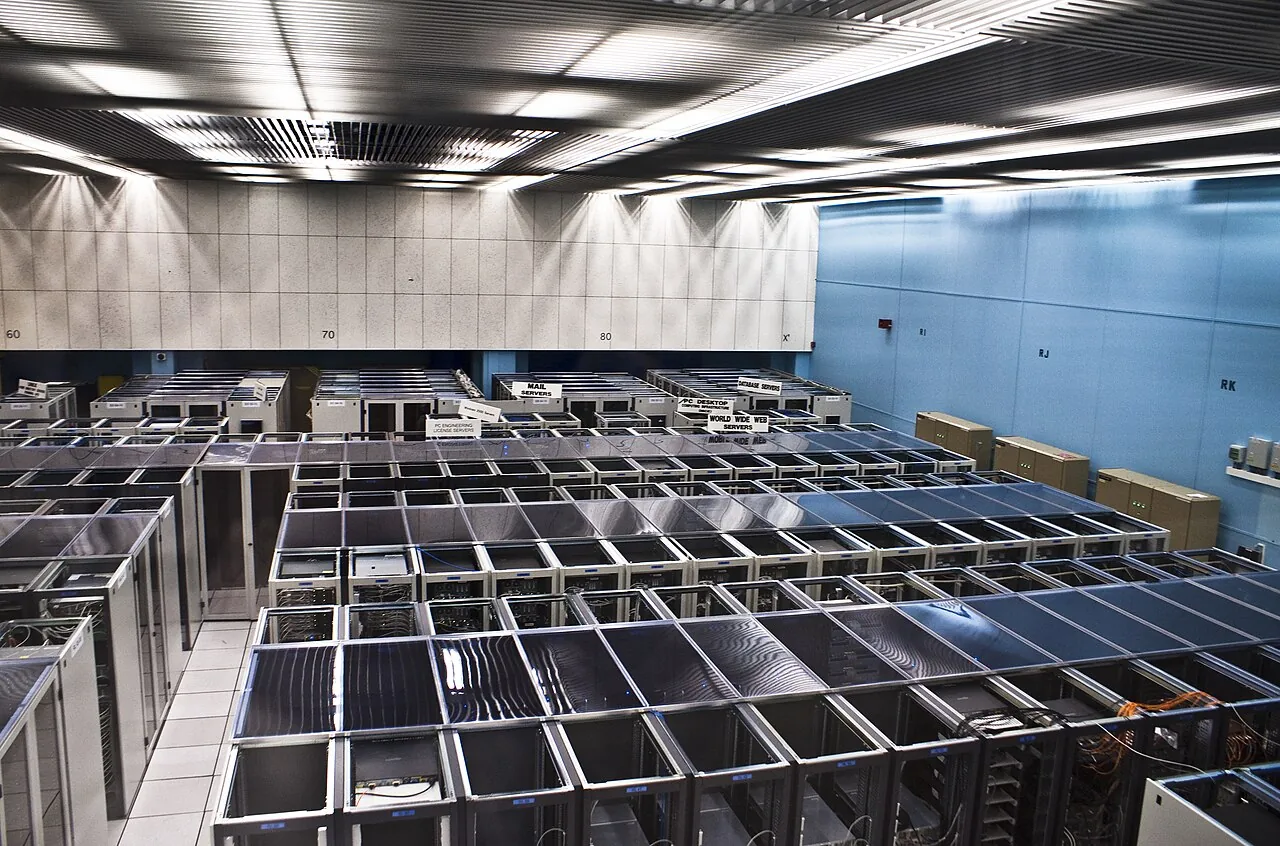
A CERN server room in Switzerland, photographed by Florian Hirzinger in February 2009. Documentary context photograph; it does not depict an Alexis Roux ZG assignment or equipment. © Florian Hirzinger · Source · CC BY-SA 3.0. Resized and converted to WebP; cropped display.
An archive is not yet a recovery procedure. It may contain code without data, one language without others, or files incompatible with the current state. Preparation means defining expected service, acceptable losses and evidence of consistency. These are planning examples, not incidents observed on this website.
Associate code, content, search indexes, media and any writable data with a version. Distinguish replaced files from subsequent writes. Record external dependencies and execution prerequisites. Keep secrets in their existing management system rather than copying them into a public archive.
Define priority tasks: reading a profile, searching, using a tool or submitting a form. Set a target duration and acceptable data loss for the context, without inventing a guarantee. Decide which defects require restoration and which permit a limited correction.
Recreate the version in a separate environment with suitable test data. Check integrity and compatibility. Disable external actions there to avoid real sends or modifications. Measure the necessary steps: an available but untested copy does not demonstrate recoverability.
Before rollback, identify received submissions, profile edits and other writes since the backup. Plan preservation or reconciliation when required. Do not replace an active database with an older copy without understanding lost data and schema dependencies.
Check browser, server and intermediary caches separately. Restored HTML may still request CSS from another version. Inspect resource URLs and suitable headers. Consult authorized logs without displaying internal details or sensitive data in visitor-facing errors.
Check HTTP responses, key pages, search, canonicals, languages and assets. Test an expected error without triggering a real action. Observe priority tasks after recovery and record limits. HTTP 200 alone proves neither correct content nor a functioning form.
Typical situations for preparing a check. They do not describe completed assignments or actual observations.
Compare document version, CSS URL and the actual file received. Inspect the relevant cache before repeated purges. Restore a coherent set and check the photographs and scripts used by that version.
Code and content have returned, but search uses another version's index. Rebuild it from the retained corpus and check queries, destinations and languages. Restoring files does not necessarily restore derived data.
List writes between backup and incident. Preserve legitimate records before replacement and check compatibility. If reconciliation is unavailable, document possible loss before deciding.
Only when it covers the necessary elements. Data, media, indexes or dependencies may live separately; identify them before claiming the version is recoverable.
First identify which layer serves the wrong version. Verify a targeted action; cache mechanisms and commands depend on hosting.
It indicates HTTP response success, not correct content or task completion. Compare against expected results.
When the defect is understood, limited and repairable without making data worse. Compare duration, effects on writes and the ability to verify each option.